
ACM source attribution: Complete full-text transcription from ACM publisher HTML, cross-checked against supplied 7-page proceedings PDF. DOI: 10.1145/3648188.3675147.
A Novel Architecture for Classical Hypertext
Authors: Mark Bernstein , Eastgate Systems, Inc., USA, bernstein@eastgate.com
Abstract
The early years of hypertext research saw a profusion of strange new hypertext models, formalisms, and systems. The exuberant abundance of this era was overwhelmed by the emergence of the Web and, later, the field's fascination with social media. Elegies to the freedom of the classical era of hypertext continue to be heard, yet novel systems are rare. This paper proposes a simple architectural twist that embeds web components — which may include hypertext systems — inside a classical hypertext framework. The goal of this work is to enable researchers to implement useful, testable prototype systems very quickly: an exotic hypertext system in an afternoon.
CCS Concepts
CCS Concepts: • Human-centered computing → Hypertext / hypermedia ;
Keywords
Classical hypertext , Tinderbox , DASH.
ACM Reference Format
ACM Reference Format: Mark Bernstein. 2024. A Novel Architecture for Classical Hypertext. In 35th ACM Conference on Hypertext and Social Media (HT '24), September 10--13, 2024, Poznan, Poland. ACM, New York, NY, USA 7 Pages. https://doi.org/10.1145/3648188.3675147
1 INTRODUCTION
Anderson and Millard's review of “Seven Hypertexts” begins by reflecting on the ACM Hypertext Conference's habit of existential doubt [3]. “Perhaps it was the advent of the World Wide Web,” they speculate, “that cast a long shadow across the wider field of Hypertext and caused such soul-searching.” Indeed, both research literature and informal discussions have been suffused with a sense that the Web prematurely foreclosed interesting and important formulations of writing with links [42, 44].
Even a superficial review of early research reveals intriguing ideas that have not been pursued because they do not readily correspond to the design of the World Wide Web [11]. Trellis explored multiwindow browsing of multimedia objects with automated reasoning about their synchronization [60]; we have more video today, but nothing like that. Indeed, much work in Web multimedia today seems dedicated to commencing and sustaining video performances that viewers do not want [20]. Scripted Documents [70] proposed user-authored, external webs (cf. Intermedia [68]), a concept reified not only by the research community [30] but also in a feral hypertexts [66] through OPML feeds and news readers. We once had hypertexts without links [65], hypertexts with multi-headed and multi-tailed links [46], hypertexts with generic links [28], and catalogs of ways to store [25] and to follow links [67].
Yet research on novel hypertext models and systems virtually disappeared from the ACM Hypertext Conference. This work was replaced by studies of social media that appeared for a time to be more directly relevant to vernacular use of the Web. Still, classical hypertext had been built on important and consequential ideas and debates about structuralism, existentialism, the perfectibility of the mind, and the nature of communication and community [18, 19]. Our studies of social media sometimes cataloged the behavior of bots and mechanical turks [5] while furthering the ambitions of villains and facilitating the surveillance of political dissidents and of women who might seek an abortion [21]. Some important knowledge was gained in the process [7], but ideas were subordinated to the profits of platform owners.
Many of the questions that classical systems sought to explore remain open. We do not know how best to write a hypertextual textbook [39] or how to assess a student's hypertext assignment [41]. We know some empirically-observed patterns found in calligraphic [12] and spatial hypertexts [16], but we don't know how to use patterns constructively or how to discover those patterns algorithmically. We know little about linking in video [58], less about linking in audio [6, 17], and still less about hypertextuality in music. Our understanding of hypertextuality in programming languages has not advanced much beyond Knuth's statement of the issue [38].
How might we find time to attack these old, familiar problems without also attacking the World Wide Web?
2 THE COST OF CLASSICAL SYSTEMS
Creating the hypertext systems of the classical era demanded substantial resources1. NLS/Augment, a major initiative of the Stanford Research Institute, ran to 100,000 lines [9] and employed more than 25 people including 11 programmers [8, 26]. Brown University's IRIS, the home of Intermedia, employed about twenty researchers. NoteCards had three lead programmers and an additional five contributors — all staff members at what was then the world's leading computer science lab [45]. Chandler, a hypertext-inflected email and calendar system backed by Lotus founder Mitch Kapor, failed despite a team of twenty-four programmers, several of them legends [56]. Resources on this scale were not easy to acquire or retain, making the early systems vulnerable to changing priorities or managerial whim. Smaller projects had to manage with whatever time their initiator could spare, or whatever volunteers the initiator could recruit [49]; the importance of personal charisma to early hypertext research should not be overlooked.
The need for prodigious resources derived in turn from the primitive state of contemporary computers, the rudimentary condition of software development, and from the wartime heritage of computing. The Xerox Alto — a high-end workstation — had a memory capacity of 512K and a 5.9MHz clock speed. An Apple Watch today has 100,000 times as much memory, and a $15 Arduino Nano has more processing power. No one used version control: Subversion 1.0 debuted in 2004. Software patterns, refactoring, and test-driven development were still a decade away, and integrated development environments were a new and controversial concept. Almost no one used package managers, and the dream of software reuse remained elusive [31]. The scarcity of access to computers (and their Cold War heritage) made humanistic applications of computing seem frivolous [32]] even though the origins of the theory of computing had been firmly rooted in the humanities [19].
Because the stakes were high, researchers often identified with their systems. You had to make design choices with care because you might not get a second chance. At the same time, it was often difficult to assess the utility of an innovative research system because the investment required to reach an acceptable level of functionality was so great. Intermedia commissioned its own costly text engine, while NoteCards piggybacked on InterLisp-D's ground-breaking visual editor. Systems built with pointer-based languages and manual memory management tended to crash; those built in LISP and Smalltalk incurred arbitrary delays for garbage collection. Arbitrary limitations were common: early Storyspace, for example, limited note titles to 32 characters, the text of writing spaces could not exceed 32K characters, and maps and outlines could not exceed 16,383 pixels in height or width [14]. Students brought books to the computer lab if they planned to use Intermedia in order to pass the time required to traverse a link [59]. If you wanted an Undo facility or a back-button, you would have to implement them from scratch. As a result, usability studies of these systems often foundered on the shoals of adventure, and persuading even developers to use system they were building could prove infeasible [56].
Today, hardly anyone can find time or resources to build a new classical hypertext system. How might we build a system as a research prototype — unfinished, unpolished — with the time and resources we can muster? Could we build a new exotic hypertext system [13] in a week? An afternoon?
3 THE POST-CLASSICAL ENVIRONMENT
Most post-classical hypertext systems have run in the web browser2. With some notable exceptions [34, 35], these systems are not intended for research, and post-classical systems are not always well represented in the research literature (though see [57] and [43]). Many post-classical systems seek to provide constructive hypertext services for a specialized task: Anki for spaced-repetition memorization, the original Wiki for debating software patterns, MediaWiki for crowd-sourcing online encyclopedias, ZigZag for viewing multidimensional structuralist dualities [4], DBpedia for browsing RDF triples.
Post-classical systems could run on a variety of machines and required little or no installation. Yet, because they run on abstract machines and in constrained sandboxes, the performance of post-classical systems can fall short. Modern computers of all sizes, including phones, have multiple cores with inhomogeneous capacities, graphic processors, and hardware specialized for machine learning; these facilities are seldom available to post-classical systems. Specialized APIs that provide access to address books, contact lists, linguistic analysis, and entity recognition are fenced off from web applications to prevent villains from covertly stealing personal data [21], but of course these resources are invaluable to hypertextual tools for thought. The phrase “Savannah Swing” might denote a person, a playlist, or a dance; access to our contact list and our music library could help a personal assistant disambiguate them [24] but no one wants to expose their taste in music or their address book to web villains. Even access to disk files is sharply constrained for post-classical systems.
Great things have been accomplished by post-classical systems, both in research [35] and in making hypertext tools available to an audience unwilling or unable to spend even modest sums [57]. Indeed, some classical systems such as NoteCards (and the entire InterLISP environment3) and Smalltalk [37] have been crafted inside the browser. More could be done. It might be interesting, for example, to reimplement Trellis, which represented hypertexts as a Petri net, in an environment with sufficient computational resources and abundant media assets [60]. Chandler was never finished [56]; if we built it now, might we learn something? If we put a modern interface on NLS, what might we find out?
4 A NEOCLASSICAL APPROACH
Rather than implement a classical hypertext system inside a Web browser, we might instead place individual Web browser panes into a classical hypertext system, putting them atop the visual representation of each hypertext node. In Figure 1, we see a Tinderbox map [15] with two notes; the second note happens to hold a live instance of NoteCards.
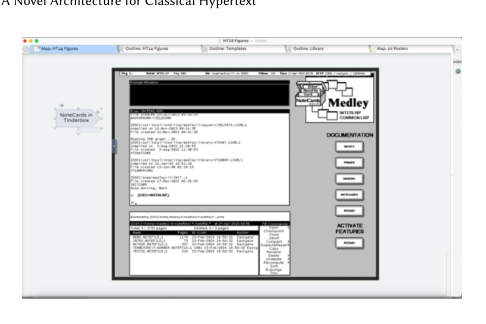
A screengrab of the Tinderbox application, in Map view, showing 2 notes. The right-hand note has image content and is in fact hosting a live instance of the NoteCards app emulated in a web page.
Figure 1: A Tinderbox map view with two notes. The larger note on the right has a poster running an instance of NoteCards.
4.1 Tinderbox
Tinderbox, a classical hypertext system, was introduced in 2001, and has maintained a modest commercial presence ever since. A Tinderbox note is an attribute-value list. Most built-in attributes — there are 462 at present — have values that are meaningful to the system: Color, for example, is the dominant color in which the note is drawn, while Width and Height represent the size of the note's bounding rectangle. Users may define additional attributes. Each attribute has a type and a default value, which notes may override. Notes are organized in a hierarchy and may inherit values from a Prototype note.
Several attributes contain Tinderbox actions, each of which is performed at a specific time. A note's Rule, for example, runs continuously, and acts as a constraint on the note. Its OnAdd action is applied to any note that is moved into the container or that is created inside it. OnAdd actions often represent preliminary estimates of the note's likely purpose; a container that holds bibliographic information for a conference paper might use the OnAdd action to configure new notes as References. Many other actions may be defined to run when a note is selected, when it is linked, and so forth. This simple action language plays a crucial role here, serving as the glue that connects the classical and post-classical elements.
A second key element of this approach is based on the Tinderbox export template facility, derived from MacWeb [48] and originally designed during a late-night discussion at Hypertext ’96. The original intention was to provide a customizable method to pour the textual content of notes into an HTML frame, substituting placeholders such as ⌃title, ⌃text, and ⌃value(expression) with information extracted from that note. This facility makes it easy to assemble information in a format that web browser panes can use.
4.2 Tinderbox Posters
Any note may ask to have a poster, a WebKit-based view that appears above the poster note's customary representation. This view, in turn, may receive its data in two ways: by fetching it from the source designated by the attribute PosterURL, or by generating it internally by applying the template designated by PosterTemplate to the note itself. The latter is what chiefly concerns us here, as it allows a poster note to collect and visualize data from other notes. For example, in Figure 2 a poster note marshals data from a container that is linked to it and presents it as a histogram. The demonstration of this affordance of DASH at Hypertext 2019 is the inspiration for the present work [64, 69].
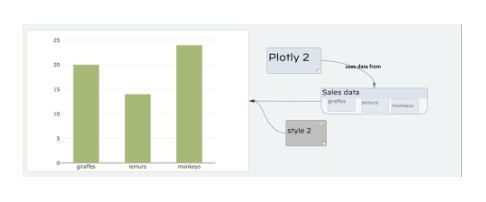
A screengrab of the Tinderbox application, in Map view, showing 4 notes. The left-hand note is a poster note shows a graph rendered using the Plotly JavaScript library and using data drawn from notes in the container shown the right of the screen.
Figure 2: A rule in the Poster note locates a container linked to that note whose name contains “data”, retrieves data from the contents and passes it to the Plotly4 library. Plotly draws a histogram in the requested style on the poster's canvas. Since rules run frequently, changes to the data are immediately reflected in the displayed visualization.
If the notes from which the poster receives data happen to change, the poster will redraw itself to reflect the update. This facility lends itself to ad hoc dashboards for keeping track of complex tasks. I might want to know, for example, how much progress I'm making on a book. In the early stages, the rate at which I'm making new notes is a plausible proxy for velocity, my rate of progress [10]. Word count of notes in the current draft of the book may be a better metric late in the game, though that may swing from a target I hope to meet to a barrier I somehow must find cuts to reach (Figure 3).
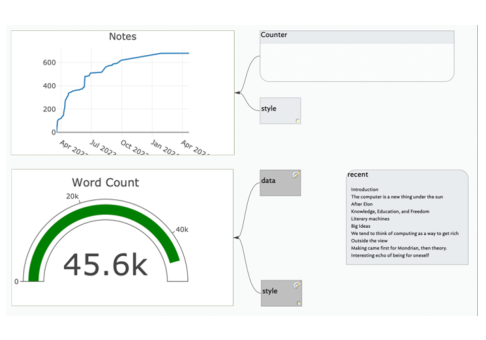
A screengrab of the Tinderbox application, in Map view, showing two different poster notes and their source data notes.
Figure 3: Poster notes lend themselves well to ad hoc dashboards.
Though many posters accept slowly changing data (such as the text of a work in progress) and present occasionally changing visualizations, posters may be more active. We may, for example, make a poster note what takes text from the Tinderbox note, runs it in a language we want to learn such as Turtle Geometry [1, 55] or Processing [53], and then animate the result (Figure 4).
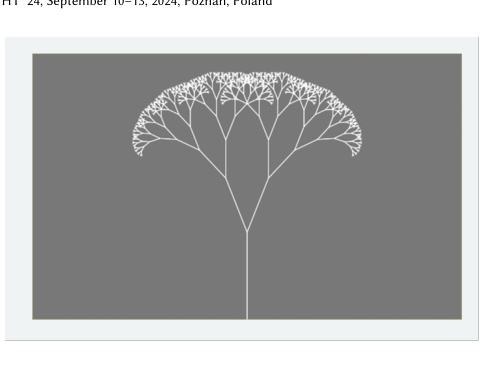
A screengrab of the Tinderbox application, in Map view, showing a poster note displaying an animated tree graph rendered using Processing.js.
Figure 4: A note that takes a program for an animation in Processing and displays the animation in its poster.
Note that the poster architecture need not create a dependency on any specific package. Figures 2 and 3 happen to use plotly, but they could just as easily use another charting library. Figure 4 uses Processing, but we might use R [62] instead. Switching libraries typically requires modest changes to data formatting. Efficient JavaScript [23] engines have given rise to myriad libraries which accept data in the form of a JSON payload and either return an HTML object ready to insert into the DOM or write into a designated canvas present in the document. In effect, the Web, in making this functional mapping f(data) ⇒ [rectangle in page layout] or f(data,DOM) ⇒ [revised DOM], has been the occasion of the first real success of software reusability.
Finally, the poster may ask its note to perform a Tinderbox action by posting the action to the TinderboxAction object, or it may request information from Tinderbox by setting a Tinderbox attribute to a JSON string. In this way, Tinderbox controls the poster but allows the poster to control Tinderbox, forming an intriguing knot. A poster about the invention of the compound bow might, when selected, rearrange the map view that contains it to bring alongside other notes about the queer ways in which people resist innovation [30, 63].
Though notes using PosterTemplate are more interesting, we might briefly observe that posters loading their contents from a PosterURL are not without interest. We might use such posters, for example, to bring together student assignments in an advanced Web Design seminar or, indeed, in any course where the work product is hypertextual (cf. The Victorian Web [40] or hypertext-based art education [61]). To support the small compass of the poster, users can inject additional CSS rules to reduce font sizes or to eliminate extraneous elements. The poster may then be surrounded by commentary, pointing out design apparent errors and exploring alternatives. Posters lend themselves to an ad hoc, localized style of adaptive hypertext; for example, style objects for each poster may refer to a configuration object that reflects user preference or competence.
4.3 Posters As Open Hypertext
The Open Hypertext movement [54] sought to liberate hypertext research from the distraction and expense of building and supporting text editors, image viewers, video players, and other media tools. By the mid-1990s, most potential users of hypertext systems owned a program for word processing; if they were going to write hypertext, they wanted to write the text with the systems they already used. Treating hypermedia as a service to be supplied by dedicated middleware could effectively separate concerns and focus the talents of hypermedia researchers on the essence of hypermedia rather than chasing bugs in text layout engines [10]. To display a chart of bird migration trends, for example, a generic image viewer might request that a middleware chart system build a graph from migration data stored at named location Ploc in the backend database. The chart program would then build an image and return it to be displayed. Clicking on the chart, in turn, might be interpreted as a request to navigate to the source of a particular data point; the chart wrapper would translate the click to a request to a navigation server which would then determine how to satisfy the user's inquiry about Western Meadowlarks in 1971.
Tinderbox posters can feel like a revival of open hypertext, plugging general-purpose visualization or presentation tools into a specialized hypermedia environment. In practice, the division of responsibilities and services tends to be less formal and less principled than in OHS. For example, posters (following DASH [64]) commonly represent their data as nodes in their classical hypertext systems rather than named locations in a backend database5. If a Tinderbox document intends to respond to changes in a poster state — if, as in Trellis, navigation to N107 in the poster should also display P13in a different poster note while starting video V1(01:37–02:14) in a new window — that logic is likely embedded in the poster or its observers within the Tinderbox document rather than in a remote media server.
5 DRAWBACKS
Posters are not tied very tightly to Tinderbox. They were not difficult to implement, and most of the work took a week. The uniformity of the Tinderbox data model, in which every attribute is defined for every note, is helpful here. A more formally-inclined system like Aquanet [46] or a duck-typed system like Chandler [56] might pose additional challenges when the poster controls the host. Some actions in these systems can only be applied to certain notes, and determining whether a given note is eligible or not might require additional work.
Browser views were designed in the expectation that one or two windows might be displayed at any time, but a map view in Tinderbox or related tools may hold hundreds of notes. This can cause some difficulties; even idle or hidden web views may create worker threads and allocate buffers to prepare for their eventual activation. Tinderbox obviates this by instantiating posters on demand, and by removing posters after their notes scroll offscreen.
The communication channel between host and poster may not be efficient. To pass data to a poster, the host may need to assemble HTML, CSS, JavaScript and JSON which the poster immediately breaks down to component structures. On the way back to the host, results are typically compiled into an XML or JSON payload from which Tinderbox extracts pertinent nuggets of information. This seems quite a lot of work, though we have not yet experienced actual performance issues.
The mutual permeability of host and poster present potential security issues, especially where the host is a research prototype. It is not apparent that these issues are in any way greater than those incurred in normal use of the host. Some web sites, however, are conspicuous targets for attack, while a novel research system is unlikely to attract the attention of nefarious or villainous attackers.
6 DISCUSSION
While preservation of hypertexts is, of course, eminently desirable, we may have lost sight of many of the concerns of early hypertext systems, questions which were not fully resolved in the classical era and which the Web seemed to have foreclosed. Late classical systems, for example, were often deeply concerned with richer, more elaborate, and more expressive links [28, 47, 51]. After the Web, we knew that a link was (and would always be) whatever Microsoft Explorer® said it was. Or so it seemed. A neoclassical system might let us quickly prototype novel links — say, links with multiple destinations — while otherwise retaining the facilities of the Web and the facilities of the classical host.
In some of the examples above (Figures 2 and 3), a poster receives its data by examining its inbound links, selecting a linked note that has the characteristics expected for a data source, and then fetching data either from that note or by iterating through its children. While pumping data through the hypertext link network is far from unprecedented, it is uncommon, and has tangential interest to the first of Halasz's seven issues: query in a hypertextual network [33].
A notable facet of the neoclassical architecture is that poster notes are literally blank slates that invite inscription, and yet at the same time offer a powerful computing environment that will be familiar to most students of computing and to many end users. One of the most impressive demonstrations of DASH was the final meeting of a course at Brown University, taught by Norm Meyrowitz and Andy van Dam: “Hypertext/Hypermedia: The Web Was Not the Beginning and the Web Is Not the End.” Undergraduate students in this course, working in small teams, extended DASH to support new note types such as timeline views. I've been building hypertext systems for a long time and I work to keep my codebase clean and simple, but adding a new note type to Tinderbox, with its 200,000 lines of C++, ObjC and Swift, might not be a reasonable term project. Building and demonstrating a novel poster note, on the other hand, should be entirely manageable.
From the earliest days of hypertext research, we have discussed scholarly notebooks and workbenches [22, 27, 29]. Notebooks have always been tricky engineering artifacts [36]. For example, a key aspect in the popularization of paper notebooks in 13th-century Italy was the observable fact that writing in ink on paper was indelible, whereas writing on the older medium, parchment, was not. This made pocket ledgers a credible and — soon — an indispensable resource for doing business [2]. At the same time, paper was sufficiently flexible to allow diagrams and artists’ sketches as well as text. Providing this combination of permanence and representational flexibility has been a challenge to crafting notebook systems; the neoclassical architecture may not make this easy, but it might make it possible.
This proposal does not impact good ideas like link servers [47, 52] or structure servers [50]. Discussions of architecture often lead to architectural astronautics, the tendency to abstract out the detail that makes a problem notable while leaving behind a plethora of boxes and arrows. Yet many questions from the classical era remain open, and some questions that seem to have been closed may have been decided prematurely. Hypertext once had big ideas, and smaller, more easily built (and discarded) systems might let us return to them.
ACKNOWLEDGMENTS
Marc Nanard, Jocelyn Nanard, and Randy Trigg were the interlocutors whose advice at Hypertext ’96 led me to discard my own inferior design; their approach made this work possible
REFERENCES
Harold Abelson. 1980. Turtle Geometry: The Computer as Medium for Exploring Mathematics. MIT Press, Cambridge, MA, USA. 498 pages. https://doi.org/10.7551/mitpress/6933.003.0001
Roland Allen. 2023. The Notebook: A History of Thinking on Paper. Profile Books, London, UK. 342 pages. https://profilebooks.com/work/the-notebook/
Mark W. R. Anderson and David E. Millard. 2023. Seven Hypertexts. In Proceedings of the 34th ACM Conference on Hypertext and Social Media: The Humanity Within (Rome, Italy) (HT ’23). Association for Computing Machinery, New York, NY, USA, Article 42, 15 pages. https://doi.org/10.1145/3603163.3609048
Mirjana Andric, Vladan Devedzic, Wendy Hall, and Leslie Carr. 2007. Keywords linking method for selecting educational web resources a la ZigZag. International Journal of Knowledge and Learning 3, 1 (2007), 30–45. https://doi.org/10.1504/IJKL.2007.012599
Jessikka Aro. 2021. Putin's Trolls: A Hybrid Memoir. Ig Publishing, New York, NY, USA. 425 pages.
Barry Arons. 1991. Hyperspeech: Navigating in Speech-only Hypermedia. In Proceedings of the Third Annual ACM Conference on Hypertext (San Antonio, TX, USA) (HYPERTEXT ’91). Association for Computing Machinery, New York, NY, USA, 133–146. https://doi.org/10.1145/122974.122989
Lars Backstrom, Cynthia Dwork, and Jon Kleinberg. 2011. Wherefore Art Thou R3579X? Anonymized Social Networks, Hidden Patterns, and Structural Steganography. Commun. ACM 54, 12 (Dec 2011), 133–141. https://doi.org/10.1145/2043174.2043199
Thierry Bardini. 2000. Bootstrapping: Douglas Engelbart, Coevolution, and the Origins of Personal Computing. Stanford University Press, Stanford, CA. 320 pages.
Belinda Barnet. 2013. Memory Machines: The Evolution of Hypertext. Anthem Press, London, UK. 192 pages.
Kent Beck. 2023. Tidy First?O'Reilly Media, Inc., Sebastopol, CA, USA. 125 pages.
Tim Berners-Lee, Robert Cailliau, Ari Luotonen, Henrik Frystyk Nielsen, and Arthur Secret. 1994. The World-Wide Web. Commun. ACM 37, 8 (aug 1994), 76–82. https://doi.org/10.1145/179606.179671
Mark Bernstein. 1998. Patterns of Hypertext. In Proceedings of the Ninth ACM Conference on Hypertext and Hypermedia: Links, Objects, Time and Space—Structure in Hypermedia Systems (Pittsburgh, PA, USA) (HYPERTEXT ’98). Association for Computing Machinery, New York, NY, USA, 21–29. https://doi.org/10.1145/276627.276630
Mark Bernstein. 2001. Card Shark and Thespis: exotic tools for hypertext narrative. In Proceedings of the 12th ACM Conference on Hypertext and Hypermedia (Århus, Denmark) (HYPERTEXT ’01). Association for Computing Machinery, New York, NY, USA, 41–50. https://doi.org/10.1145/504216.504233
Mark Bernstein. 2002. Storyspace 1. In Proceedings of the Thirteenth ACM Conference on Hypertext and Hypermedia (College Park, MD, USA) (HYPERTEXT ’02). Association for Computing Machinery, New York, NY, USA, 172–181. https://doi.org/10.1145/513338.513383
Mark Bernstein. 2003. Collage, Composites, Construction. In Proceedings of the Fourteenth ACM Conference on Hypertext and Hypermedia (Nottingham, UK) (HYPERTEXT ’03). Association for Computing Machinery, New York, NY, USA, 122–123. https://doi.org/10.1145/900051.900077
Mark Bernstein. 2011. Can We Talk about Spatial Hypertext?. In Proceedings of the 22nd ACM Conference on Hypertext and Hypermedia (Eindhoven, Netherlands) (HT ’11). Association for Computing Machinery, New York, NY, USA, 103–112. https://doi.org/10.1145/1995966.1995983
Mark Bernstein. 2018. As We May Hear: Our Slaves of Steel II. In Proceedings of the 29th ACM Conference on Hypertext and Social Media (Baltimore, MD, USA) (HT ’18). Association for Computing Machinery, New York, NY, USA, 242–245. https://doi.org/10.1145/3209542.3210575
Mark Bernstein. 2022. On The Origins Of Hypertext In The Disasters Of The Short 20th Century. In Proceedings of the ACM Web Conference 2022 (Lyon, France (Virtual)). Association for Computing Machinery, New York, NY, USA, 3450–3457. https://doi.org/10.1145/3485447.3512280
Mark Bernstein. 2024. Thinking in Tinderbox. Eastgate Systems Inc., Watertown, MA, USA.
Mark Bernstein and Clare Hooper. 2018. A Villain's Guide to Social Media and Interactive Digital Storytelling Interactive Storytelling. In 11th International Conference on Interactive Digital Storytelling (Dublin, Ireland). Springer International Publishing, Cham, CH, 50–61. https://doi.org/10.1007/978-3-030-04028-4_4
Mark Bernstein and Clare Hooper. 2018. A Villain's Guide To Social Media And Web Science. In Proceedings of the 29th ACM Conference on Hypertext and Social Media (Baltimore, MD, USA) (HT ’18). Association for Computing Machinery, New York, NY, USA, 246–250. https://doi.org/10.1145/3209542.3210576
Andrew M. Burger, Barry D. Meyer, Cindy P. Jung, and Kevin B. Long. 1991. The Virtual Notebook System. In Proceedings of the Third Annual ACM Conference on Hypertext (San Antonio, TX, USA) (HYPERTEXT ’91). Association for Computing Machinery, New York, NY, USA, 395–401. https://doi.org/10.1145/122974.125119
Douglas Crockford. 2008. JavaScript: The Good Parts: The Good Parts. O'Reilly Media, Inc., Sebastopol, CA, USa. 174 pages.
Bud Culligan. 2011. Making Knowledge Navigator. Dubberly Design Office. Retrieved May 4, 2024 from https://www.dubberly.com/articles/how-the-knowledge-navigator-video-came-about.html
Hugh C. Davis. 1998. Referential Integrity of Links in Open Hypermedia Systems. In Proceedings of the Ninth ACM Conference on Hypertext and Hypermedia: Links, Objects, Time and Space—Structure in Hypermedia Systems (Pittsburgh, PA, USA) (HYPERTEXT ’98). Association for Computing Machinery, New York, NY, USA, 207–216. https://doi.org/10.1145/276627.276650
Douglas Carl Engelbart. 1972. Advanced Intellect-Augmentation Techniques. NASA Contractor Report CR-1827. Technical Report. Stanford Research Institute. https://ntrs.nasa.gov/citations/19720011592
Thomas Erickson. 1996. The design and long-term use of a personal electronic notebook: a reflective analysis. In Proceedings of the SIGCHI Conference on Human Factors in Computing Systems (Vancouver, British Columbia, Canada) (CHI ’96). Association for Computing Machinery, New York, NY, USA, 11–18. https://doi.org/10.1145/238386.238392
Andrew M. Fountain, Wendy Hall, Ian Heath, and Hugh C. Davis. 1990. MICROCOSM: An Open Model for Hypermedia with Dynamic Linking. In Proceedings of the European Conference on Hypertext: Hypertext: Concepts, Systems and Applications (INRIA, Paris, France) (ECHT ’90). Association for Computing Machinery, New York, NY, USA, 298–311.
Jerry Fowler, Donald G. Baker, Ross Dargahi, Vram Kouramajian, Hillary Gilson, Kevin Brook Long, Cynthia Petermann, and G. Anthony Gorry. 1994. Experience with the virtual notebook system: abstraction in hypertext. In Proceedings of the 1994 ACM Conference on Computer Supported Cooperative Work (Chapel Hill, NC, USA) (CSCW ’94). Association for Computing Machinery, New York, NY, USA, 133–143. https://doi.org/10.1145/192844.192892
Richard Furuta, Frank M. Shipman, III, Catherine C. Marshall, Donald Brenner, and Haowei Hsieh. 1997. Hypertext Paths and the World-Wide Web: Experiences with Walden's Paths. In Proceedings of the Eighth ACM Conference on Hypertext. ACM, Southampton, United Kingdom New York, NY, USA, 167–176. https://doi.org/10.1145/267437.267455
Richard P. Gabriel. 1996. Patterns of Software: Tales from the Software Community. Oxford University Press, USA, New York, NY, USA.
Bernard Dionysius Geoghegan. 2022. Code: From Information Theory to French Theory. Duke University Press, Durham, NC, USA. 182 pages.
Frank G. Halasz. 2001. Reflections on “Seven Issues”: Hypertext in the Era of the Web. ACM Journal of Computer Documentation (JCD) 25, 3 (2001), 109–114. https://doi.org/10.1145/507317.507328
Heiko Haller and Andreas Abecker. 2010. iMapping – A Zooming User Interface Approach for Personal and Semantic Knowledge Management. In Proceedings of the 21st ACM Conference on Hypertext and Hypermedia (Toronto, ON, Canada) (HT ’10). Association for Computing Machinery, New York, NY, USA, 119–128. https://doi.org/10.1145/1810617.1810638
Charlie Hargood, Mark J. Weal, and David E. Millard. 2018. The StoryPlaces Platform: Building a Web-Based Locative Hypertext System. In Proceedings of the 29th ACM Conference on Hypertext and Social Media (Baltimore, MD, USA) (HT ’18). Association for Computing Machinery, New York, NY, USA, 128–135. https://doi.org/10.1145/3209542.3209559
Jillian M. Hess. 2022. How Romantics and Victorians Organized Information: Commonplace Books, Scrapbooks, and Albums. Oxford University Press, Oxford, UK. 320 pages. https://doi.org/10.1093/oso/9780192895318.001.0001
Dan Ingalls. 2020. Welcome to the Smalltalk Zoo. The Computer History Museum. Retrieved May 4, 2024 from https://smalltalkzoo.thechm.org
Donald Ervin Knuth. 1992. Literate Programming. The University of Chicago Press, Chicago, IL, USA. 384 pages.
George P. Landow. 1987. Relationally Encoded Links and the Rhetoric of Hypertext. In Proceedings of the ACM Conference on Hypertext (Chapel Hill, NC, USA) (HYPERTEXT ’87). Association for Computing Machinery, New York, NY, USA, 331–343. https://doi.org/10.1145/317426.317450
George P. Landow. 2011. The Victorian Web and the Victorian Course Wiki: Comparing the Educational Effectiveness of Identical Assignments in Web 1.0 and Web 2.0. In Proceedings of the 22nd ACM Conference on Hypertext and Hypermedia (Eindhoven, Netherlands) (HT ’11). Association for Computing Machinery, New York, NY, USA, 305–312. https://doi.org/10.1145/1995966.1996006
George P. Landow and Paul Kahn. 1992. Where's the Hypertext: The Dickens Web As a System-independent Hypertext. In Proceedings of the ACM Conference on Hypertext (Milan, Italy) (ECHT ’92). Association for Computing Machinery, New York, NY, USA, 149–160. https://doi.org/10.1145/168466.168515
John J. Leggett. 1998. Camping on Banks of the Hypermedia Literature: Waiting for (a Hyperliterate) Civilization to Arrive. In Proceedings of the Ninth ACM Conference on Hypertext and Hypermedia: Links, Objects, Time and Space—Structure in Hypermedia Systems (Pittsburgh, PA, USA) (HYPERTEXT ’98). Association for Computing Machinery, New York, NY, USA, 305. https://doi.org/10.1145/276627.276671
Bo Leuf and Ward Cunningham. 2001. The Wiki Way: Quick Collaboration on The Web. Addison-Wesley Boston, MA, New York, NY. 435 pages.
Paul H. Lewis, Wendy Hall, Les A. Carr, and David C. De Roure. 1999. The Significance of Linking. ACM Computing Surveys (CSUR) 31, 4es (1999), 10. https://doi.org/10.1145/345966.345992
Catherine C Marshall. 1986. NoteCards™ Release 1.2 Reference Manual. Technical Report. Xerox Corporation. https://interlisp.org/documentation/notecards_user_guide_v1.2.pdf
Catherine C. Marshall, Frank G. Halasz, Russell A. Rogers, and William C. Janssen, Jr.1991. Aquanet: A Hypertext Tool to Hold Your Knowledge in Place. In Proceedings of the Third Annual ACM Conference on Hypertext (San Antonio, TX, USA) (HYPERTEXT ’91). Association for Computing Machinery, New York, NY, USA, 261–275. https://doi.org/10.1145/122974.123000
Danius T. Michaelides, David E. Millard, Mark J. Weal, and David. DeRoure. 2002. Auld Leaky: A Contextual Open Hypermedia Link Server. In Hypermedia: Openness, Structural Awareness, and Adaptivity (Aarhus, Denmark). Springer, Cham, CH, 59–70. https://doi.org/10.1007/3-540-45844-1_6
Jocelyne Nanard and Marc Nanard. 1993. Should Anchors Be Typed Too? An Experiment with MacWeb. In Proceedings of the Fifth ACM Conference on Hypertext (Seattle, WA, USA) (HYPERTEXT ’93). Association for Computing Machinery, New York, NY, USA, 51–62. https://doi.org/10.1145/168750.168767
Theodor Holm Nelson. 1982. Literary Machines. Mindfull Press, Sausalito, CA, USA.
Peter J. Nürnberg, Kaj Grønbæk, Dirk Bucka-Lassen, Claus Aagaard Pedersen, and Olav Reinert. 1999. A component-based open hypermedia approach to integrating structure services. New Review of Hypermedia and Multimedia 5, 1 (1999), 179–205. https://doi.org/10.1080/13614569908914713
Peter J. Nürnberg, John J. Leggett, and Erich R. Schneider. 1997. As We Should Have Thought. In Proceedings of the Eighth ACM Conference on Hypertext (Southampton, UK) (HYPERTEXT ’97). Association for Computing Machinery, New York, NY, USA, 96–101. https://doi.org/10.1145/267437.267448
A. Pearl. 1989. Sun's Link Service: A Protocol for Open Linking. In Proceedings of the Second Annual ACM Conference on Hypertext (Pittsburgh, PA, USA) (HYPERTEXT ’89). Association for Computing Machinery, New York, NY, USA, 137–146. https://doi.org/10.1145/74224.74236
Casey Reas and Ben Fry. 2006. Processing: programming for the media arts. AI & SOCIETY 20, 4 (2006), 526–538. https://doi.org/10.1007/s00146-006-0050-9
Siegfried Reich, Uffe K. Will, Peter J. Nürnberg, Hugh C. Davis, Kaj Grønbæk, Kenneth M. Anderson, David E. Millaerd, and M. Haake, Jörg. 1999. Addressing interoperability in open hypermedia: the design of the open hypermedia protocol. New Review of Hypermedia and Multimedia 5, 1 (1999), 207–248. https://doi.org/10.1080/13614569908914714
Mitchel Resnick. 1997. Turtles, Termites, and Traffic Jams: Explorations in Massively Parallel Microworlds. MIT Press, Cambridge, MA, USA. 184 pages.
Scott Rosenberg. 2007. Dreaming in Code: Two Dozen Programmers, Three Years, 4,732 Bugs, and One Quest for Transcendent Software. Crown, New York, NY, USA. 416 pages.
Anastasia Salter and Stuart Moulthrop. 2021. Twining: Critical and Creative Approaches to Hypertext Narratives. Amherst College Press, Amherst, MA, USA. 432 pages. https://doi.org/10.3998/mpub.12255695
Nitin Sawhney, David Balcom, and Ian Smith. 1996. HyperCafe: Narrative and Aesthetic Properties of Hypervideo. In Proceedings of the Seventh ACM Conference on Hypertext: Docuverse Takes Form (Bethesda, MD, USA) (HYPERTEXT ’96). Association for Computing Machinery, New York, NY, USA, 1–10. https://doi.org/10.1145/234828.234829
Karen E. Smith and Stanley B. Zdonik. 1987. Intermedia: A Case Study of the Differences between Relational and Object-Oriented Database Systems Conference. In Conference Proceedings on Object-Oriented Programming Systems, Languages and Applications (Orlando, FL, USA). Association for Computing Machinery, New York, NY, USA, 452–465. https://doi.org/10.1145/38765.38849
P. David Stotts and Richard Furuta. 1989. Petri-net-based Hypertext: Document Structure with Browsing Semantics. ACM Transactions on Information Systems (TOIS) 7, 1 (1989), 3–29. https://doi.org/10.1145/64789.64791
Pamela Goode Taylor. 1999. Hypertext-based Art Education: Implications for Liberatory Learning in High School. Eastgate, Inc. Retrieved May 4, 2024 from http://www.eastgate.com/storyspace/art/Taylor1.html
R Core Team. 2013. R: A language and environment for statistical computing. https://www.r-project.org/about.html
The Atlantic 1945. As We May Think. The Atlantic Monthly 176, 1 (1945), 101–108 pages.
Andries van Dam. 2019. Reflections on a Half-Century of Hypertext. In Proceedings of the 30th ACM Conference on Hypertext and Social Media: Tear Down The Wall (Hof, Germany) (HT ’19). Association for Computing Machinery, New York, NY, USA, 3–4. https://doi.org/10.1145/3342220.3344782
H. Van Dyke Parunak. 1991. Don't link me in: set based hypermedia for taxonomic reasoning. In Proceedings of the Third Annual ACM Conference on Hypertext (San Antonio, TX, USA) (HYPERTEXT ’91). Association for Computing Machinery, New York, NY, USA, 233–242. https://doi.org/10.1145/122974.122998
Jill Walker. 2005. Feral Hypertext: When Hypertext Literature Escapes Control. In Proceedings of the Sixteenth ACM Conference on Hypertext and Hypermedia (Salzburg, Austria). Association for Computing Machinery, New York, NY, USA, 46–53. https://doi.org/10.1145/1083356.1083366
E. James Whit Whitehead. 2002. Uniform Comparison of Data Models Using Containment Modeling. In Proceedings of the Thirteenth ACM Conference on Hypertext and Hypermedia (College Park, MD, USA) (HYPERTEXT ’02). Association for Computing Machinery, New York, NY, USA, 182–191. https://doi.org/10.1145/513338.513384
Nicole Yankelovich, Bernard J. Haan, Norman K. Meyrowitz, and Steven M. Drucker. 1988. Intermedia: The Concept and the Construction of a Seamless Information Environment. Computer 21, 1 (1988), 81–96. https://doi.org/10.1109/2.222120
Stanley Yip, Bob Zeleznik, Samuel Wilkins, Tyler Schicke, and Andries van Dam. 2020. Dash: A Hyper Framework. In Proceedings of the 31st ACM Conference on Hypertext and Social Media: HYPERTEXT for Social Good (Orlando, FL, USA (virtual)) (HT’20). Association for Computing Machinery, New York, NY, USA, 237–238. https://doi.org/10.1145/3372923.3404807
P. T. Zellweger. 1989. Scripted Documents: A Hypermedia Path Mechanism. In Proceedings of the Second Annual ACM Conference on Hypertext (Pittsburgh, PA, USA) (HYPERTEXT ’89). Association for Computing Machinery, New York, NY, USA, 1–14. https://doi.org/10.1145/74224.74225
FOOTNOTE
1That this account of the economics of classical hypertext systems is anecdotal is regrettable but inevitable. The finances of early hypertext development were inextricably bound up with those of their host organizations, not to mention government and foundation grants whose ultimate sources were, in some instances, state secrets [32]. There is, moreover, no uniform method to account for the contributions of unique individual talents. How does your general ledger account for the presence of Richard M. Stallman or Bill Atkinson?
2An important exception of particular interest to the neoclassical hypertext endeavor was the effort to construct component-based open hypertext systems (OHS) [54]. Early hypertext systems had built their own viewers and editors for text, images, and videos. This was expensive and distracting; OHS promised to augment whatever editor the user preferred to use with a hypermedia-enabling wrapper which would, in turn, communicate with middleware servers in which the semantics of links (including collaborative links among user sessions) would be managed. OHS was deeply interested in a principled separation of concerns embodied in the middleware layer: a spatial server, a navigation server, and a collaboration server might all be expected to engage the same client, perhaps at the same time. This also provided a practical separation of concerns into chunks commensurable with the size of a doctoral dissertation.
4Plotly Technologies Inc. Collaborative data science. Montréal, QC, 2015. https://plot.ly.
5This design decision is, perhaps, not completely unprincipled. Tinderbox's prototype inheritance is used heavily in Tinderbox and therefore must be fast. A complex map view might require tens of thousands of attribute references, and composing an HTML export can require millions. That's a lot of backend queries.
Permission to make digital or hard copies of all or part of this work for personal or classroom use is granted without fee provided that copies are not made or distributed for profit or commercial advantage and that copies bear this notice and the full citation on the first page. Copyrights for components of this work owned by others than the author(s) must be honored. Abstracting with credit is permitted. To copy otherwise, or republish, to post on servers or to redistribute to lists, requires prior specific permission and/or a fee. Request permissions from permissions@acm.org.
HT '24, September 10–13, 2024, Poznan, Poland
© 2024 Copyright held by the owner/author(s). Publication rights licensed to ACM.
ACM ISBN 979-8-4007-0595-3/24/09.
Do you like what you are reading? Subscribe to receive updates.
Unsubscribe anytime